Start from an image when the shot needs to resemble a specific product, person or approved composition. Start from text when you want the model to explore the look. Neither guarantees continuity: an image anchors the starting view, but labels, faces and newly revealed surfaces can still change as the shot moves.
Choose per shot. A product close-up may need a reference; an abstract background may not. If exact lettering matters, keep it as a separate graphic rather than asking the video model to redraw it.
Jump to: input comparison · choose by deliverable · matched trial · multi-shot workflow
What each input fixes, and what it leaves free
In first-frame image-to-video, the supplied image conditions the starting appearance and composition. That gives the model visual information a text description cannot specify precisely, but it does not guarantee faithful detail throughout the clip.
The Adaptive Low-Pass Guidance research offers one explanation for weak motion in some image-conditioned models: fine image detail can bias generation toward a static result. Its authors studied specific open models, including Wan 2.1; this is not proof that every commercial model behaves identically.
Without visual references, the prompt leaves identity and composition to the model. Those choices can vary between runs. That is the point when you want variety and the problem when you want the same product twice.
The full range of starting points, as the current models expose them:
| Starting point | Constrains | Leaves to the model | Typical failure |
|---|---|---|---|
| Text only | Mood, subject class, camera intent | Everything visual, including identity | A different product or face every run |
| Single image (first frame) | Frame 0: identity, composition, lighting, label | All motion, and everything the camera reveals | Barely moves, or moves the wrong thing; invents what is off-frame |
| First and last frame | Frame 0 and frame N | The path between them | A cut instead of a move if the frames differ too much |
| Reference images | Who or what appears, across shots | Framing and motion | Softer identity than a first frame |
| Reference video | Timing, blocking, camera path, performance | Appearance, if you are swapping it | Single-subject limits; output length equals the source |
| Extend | Continuity from the last second | New content | Drift accumulates |
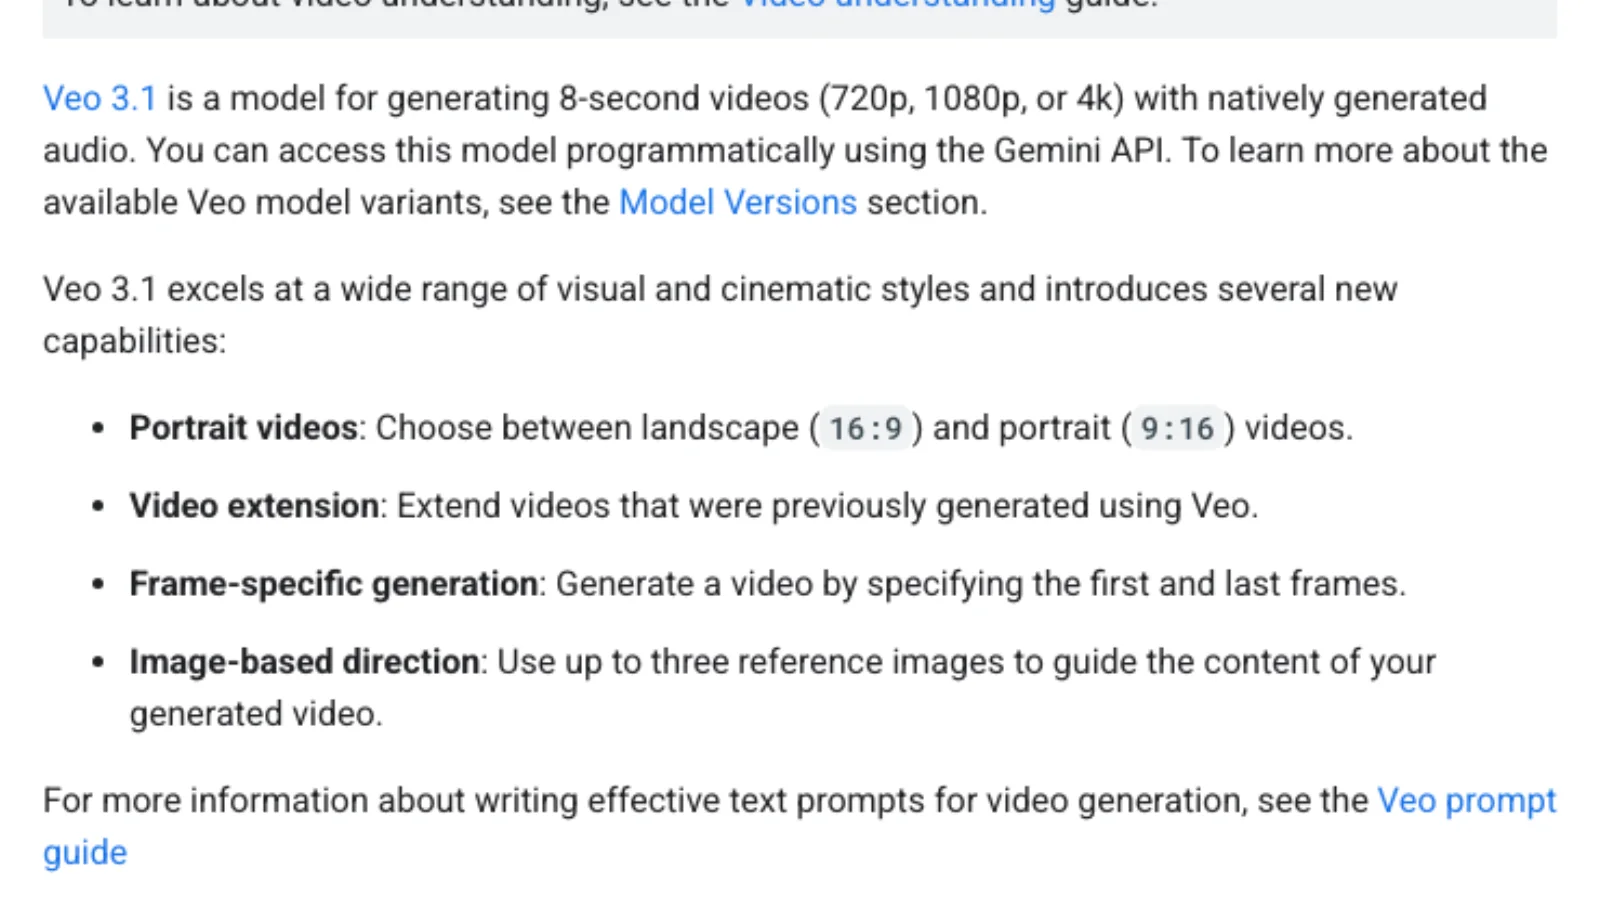
Input modes vary by model and endpoint. Google's Veo documentation, for example, distinguishes first-frame generation, first-and-last frames, reference images and extension. Check the exact mode you plan to use; a model accepting an image does not mean every image workflow is supported.
By deliverable
| Deliverable | Start from | Why | Expect this to go wrong |
|---|---|---|---|
| Product shot, specific SKU | The approved packshot; first and last frame for a turn or reveal; reference images to carry the SKU into other shots | The packshot supplies the intended label, proportions and colour | The label drifts when the product rotates or leaves frame; a pull-back invents the room |
| Concept or mood piece | Text, on a model with native audio | Identity does not matter; variance is a feature | Motion or composition misses the brief despite a plausible look |
| Talking presenter | An approved headshot plus lip-synced native audio, or a reference-video performance transfer | The image supplies appearance; a performance reference can supply delivery | Drift on big expressions and on small faces |
| Logo or type animation | Neither. Generate a background plate from an image and overlay the mark in an editor | Exact lettering is easier to preserve as an editable graphic | Garbled glyphs, warped marks |
| UGC-style ad | A real phone photo of the product; a reference video for pacing; text only for cutaways | Authenticity is a specific product in a specific hand | The product changes between clips |
| Explainer | Text for B-roll, reference images for the recurring object, first and last frame for transitions; keep charts and text out of generation | Cheap variety where nobody checks identity | Extra objects appear; the set changes between clips |
| Social loop | First and last frame, with frame N close to frame 0 | Loops need the bookends to match | A visible cut when the bookends differ |
Two rows deserve a longer note.
Product shots. The image gets you the right product in frame 0. It does not guarantee the right product in frame 60, and two risks to check are rotation and reveals. A packshot animated into a slow turn shows the model the front of the box and asks it to invent the sides. A pull-back starts inside the image and ends outside it. Kling's own camera guide puts it directly: a pull-back "needs a clear starting subject and a clear revealed environment. If the scene is too abstract, the model may not know what to reveal" (Kling). The practical rule: an image provides evidence for the visible surfaces, while newly revealed areas need to be inferred. For a turn, give a first and last frame. For a reveal, either describe the room precisely or accept that it will be generated. And for lettering specifically, restore the type in the editor afterwards rather than trusting any model to hold it; Alibaba says of Wan 3.0 that on-screen text is "not yet where we want" (Alibaba Cloud blog), so do not treat a plausible first frame as verification of the whole label.
Presenters. A headshot plus a model with native speech, such as Kling 3.0 or Veo 3.1, conditions the face while generating delivery. A reference video, through Runway's Act-Two or Kling's Motion Control, gets you a real performance mapped onto the face (Runway changelog, Kling Motion Control). Identity drift within a clip is worst with large expression changes and when the face is small in frame; a CVPR 2026 paper on identity-preserving generation documents both (arXiv 2510.14255). Frame the presenter large and keep each clip short.
Where image-to-video fails
It barely moves. First-frame conditioning can favor the still's appearance over large motion. The Adaptive Low-Pass Guidance paper describes a "shortcut trajectory that overfits to the static appearance of the reference image" and measures a drop in motion on standard benchmarks for image-conditioned generation compared with text (ALG). That is one possible cause of a clip that looks like a photograph with a slight breeze; the model, input and prompt also matter. Prompting for motion explicitly helps. So does choosing a still with implied motion: a figure mid-stride animates more readily than one standing square to camera.
The prompt fights the image. Re-describing what is in the still gives the model two versions of the subject, and they disagree. PixVerse's prompt guide describes the result as silhouette changes, material alteration and repositioned detail, and recommends focusing on motion and constraints rather than repeating the image description (PixVerse). Runway's guide says the same: image-to-video prompts should describe motion, not re-describe the image (Runway Academy).
The camera reveals what the image never showed. Covered above, and worth repeating as a rule: the more the camera moves, the less the image is doing.
First and last frames that do not match. Kling's guidance on start and end frames is that the two images should be "as similar as possible, as significant differences may cause a lens switch" (Kling), meaning the model cuts between them instead of moving between them. Bookends work for a turn, a lighting change or a loop. They do not work as a substitute for two shots.
Where text-to-video fails
The difficult cases are repeatable identity, exact lettering and continuity between separately generated clips.
The first is the obvious one: text alone does not provide a reliable reference for a particular product, face or logo. The second follows from it: if the brief requires exact pack lettering, verify it frame by frame or composite the approved lettering separately. The third is the one that catches people who have had one good result. Text-to-video is judged on a single clip, and a single clip can be excellent. A second run of the same prompt can change the product or room. Text is the right starting point for the shots where that does not matter, which is more of them than you might think: establishing shots, texture, abstract motion, cutaways, anything nobody will compare frame to frame.
The third option: a reference video
When timing or performance must follow a specific take, a reference video can be more precise than a description or still. There are three distinct jobs here, and they are often lumped together:
- Performance or motion transfer onto an image. A human take drives a character or a product. Runway's Act-Two takes a performance video and a character image (Runway); Kling's Motion Control takes a 3 to 30 second reference video and a character image, and requires a single, fully visible subject (Kling). Output length follows the source.
- Restyle or edit an existing clip while keeping its motion. Luma's Modify Video keeps the source's motion and swaps appearance, up to 20 seconds, with output matching the source length (Luma). Runway's Aleph 2.0 edits a frame and propagates it (Runway).
- Reference bundles that guide several aspects of a shot. Check the chosen model's documentation for what each input controls; an appearance reference is not necessarily a motion reference.
Choose a reference video when timing or a human performance is the thing you cannot put into words. Expect single-subject constraints and a duration cap.
Compare two starting points on one shot
Use one deliverable and one model version that supports both modes. Keep duration, aspect ratio and intended motion the same. Try several outputs per mode rather than treating one lucky sample as the winner.
For text-to-video, describe the subject, setting and motion. For image-to-video, attach the approved composition and focus the prompt on motion. Record those differences: this is a comparison of practical workflows, not a controlled experiment isolating every model variable.
Score the outputs against three questions: does the subject remain recognizable, does the requested motion happen, and how much repair is needed? Inspect the middle and end as well as the first frame. Record failed runs and credits, including the cost of creating the input still. This article provides the decision framework; it does not report results from this trial.
What this means for a multi-shot cut
Most real jobs use all of the above, and the decision is per shot, not per project. A workable sequence:
- Settle the subject as reference images before generating any video: the product renders, the presenter's headshot, the recurring object.
- Make one still per shot from those references, so composition and identity are decided while they are cheap to change.
- Animate each still with image-to-video, prompting only for motion.
- Chain shots by feeding one clip's last frame as the next clip's first frame, or by extending. Veo 3.1 extends by seven seconds up to twenty times, at 720p (Gemini API docs).
- Keep clips short and re-anchor often. Drift compounds within a clip, so a cut every few seconds costs less than a long take that wanders. This only pays off if the tool keeps each shot separate afterwards, which is the first of the four questions to ask any tool.
The alternative is a single-pass multi-shot generation: Kling 3.0's storyboard mode, or the 30-second single passes that Seedance 2.5 and Wan 3.0 now offer. Less control per shot, one run instead of eight. It suits concept pieces and suits product work poorly, for the same reasons as text-to-video.
This is the work an agent is for: holding the reference set, deciding the starting point per shot, and re-anchoring automatically. It is also why a brief names the assets that are fixed: those become the references, and everything else becomes text. Voyager plans at that level. It does not change what any model accepts, and it is in private preview, so treat the sequence above as the method and the product as one way to run it.
One model to leave off the list: OpenAI's Sora app and web service were discontinued in April 2026, with the API scheduled to close on 24 September 2026 (OpenAI). It is therefore a poor starting point for a workflow you want to keep using.
Frequently asked questions
Is image-to-video better than text-to-video? It locks the first frame. That is better only when you have a frame worth locking: a product, a face, a composition you have already approved. For a mood piece or a cutaway, the lock is a constraint you do not need.
Why does my image-to-video clip barely move? Because the same mechanism that preserves your still also biases the model toward keeping it still. Prompt the motion explicitly, pick a source image with motion implied in it, and do not re-describe the subject in the prompt.
How do I keep the same product or character across several clips? With reference images, not descriptions. Generate a still per shot from the same references, animate each one, and chain them by last frame or extension. Keep each clip short so drift has less time to accumulate.
When does first-and-last-frame beat a single image? For a turn, a transition, a before-and-after, or a loop, where you know both ends and want the model to find the path. It fails when the two frames are too different to be one shot, in which case you get a cut.
What does a reference video actually control? Timing, blocking, camera path and, for performance transfer, the acting. What transfers depends on the model and mode. Check subject-count constraints, duration and whether appearance is preserved or replaced.
Why does the label change when the product turns or the camera pulls back? The image only fixed the side of the product you showed and the part of the room inside the frame. Rotation and reveals ask the model to invent the rest. Use a first and last frame for turns, describe the reveal precisely, and restore lettering in the editor.
Make your next project in Voyager
Create an account, download Voyager, and start making.